On this page
- The three words everyone mixes up
- Three words, three questions
- Question one: how do we write to disk?
- The write path
- The read path, and the Bloom filter
- The trade-off has a name: amplification
- Question two: how do we search?
- Question three: where does the row live?
- What InnoDB and Postgres actually do
- Why this changes how you design
- Where I got it wrong
- Who picks the route: the optimizer and its statistics
- Reading a wrong plan
- When the full scan is the right answer
- Three mantras
The three words everyone mixes up
I was reading chapter 3 of Designing Data-Intensive Applications (first edition) for the second time when a senior colleague, the kind of DBA who keeps his notes in plain text files, asked me a casual question: "So is your primary key index clustered, and is it a B-Tree?" I opened my mouth to answer and realised I did not know whether those were two questions or one. LSM-Tree, B-Tree, clustered index: I had them filed in one drawer labelled "how databases store stuff", and that single drawer was the whole problem.
This post is the one I wish I had read before that conversation. The claim is short: these three terms answer three different questions, so they do not compete with each other. A single index can be a B-Tree and clustered at the same time, and a storage engine can be an LSM-Tree while still giving you something that behaves like an index. After the three concepts we go to the part that actually decides whether your query is fast on Monday morning: the query optimizer and the statistics it trusts.
Three words, three questions
So let us take the drawer apart. Here is the whole post in one table. If you only keep this, you already have the part I got wrong for years.
| The question | The concept | The answer in one line | Image |
|---|---|---|---|
| How do we write to disk? | LSM-Tree vs update-in-place pages | Append sequentially, sort and merge later | A journal vs an accounting ledger |
| How do we search? | B-Tree | Descend a shallow tree of sorted pages: 3 to 4 steps | Thumb-index tabs on a dictionary |
| Where does the row live? | Clustered vs secondary | Row inside the leaf, or only a pointer to it | A dictionary vs the index at the back of a book |
- separate questions
- 3
- B-Tree levels, millions to billions of rows
- 3-4
- clustered index per table
- 1
- descents for an InnoDB secondary lookup
- 2
Question one: how do we write to disk?
Start with the first row of that table. Picture two ways to keep a shop's money. A journal: every sale is a new line at the bottom of the page, never erased, never revisited. And an accounting ledger: every account has its own cell, and when a number changes you find the cell and overwrite it. The journal is trivially fast to write, because the pen never travels. The ledger is fast to read, because each answer sits in one known place. Storage engines face exactly this choice.
The ledger is the update-in-place family: B-Trees, in Postgres, MySQL, Oracle, SQL Server. The journal is the log-structured family: the LSM-Tree (log-structured merge-tree), behind RocksDB, LevelDB, Cassandra, HBase. Kleppmann devotes the first half of chapter 3 to the journal side, starting from a plain append-only file and building up to an LSM-Tree one fix at a time.
The write path
- WAL. The write is appended to a write-ahead log on disk first, purely so a crash cannot lose it. Sequential, cheap.
- Memtable. The write also goes into a sorted in-memory structure (a balanced tree or skip list). Memory speed.
- SSTable. When the memtable passes a size threshold (RocksDB defaults to 64 MB), it is flushed as one immutable sorted file, a Sorted String Table. No file is ever edited again.
- Compaction. A background process merge-sorts SSTables into bigger ones, discarding overwritten values along the way and, once it is safe, deleted keys (tombstones).
Notice what is missing: nothing is ever written in the middle of an existing file. Every disk write is sequential, which is what disks and SSDs like best. That is the entire trick.
The read path, and the Bloom filter
The price is on the read side. A key may be in the memtable, or in any of several SSTables, and the newest copy wins, so a naive lookup may have to check them all. The fix is a Bloom filter per SSTable: a compact bit array that answers "is key K in this file?" with either "definitely not" or "maybe". It never produces a false negative; it produces false positives at a rate you choose (roughly 1% at 10 bits per key, the figure RocksDB documents as a common setting). One cheap in-memory check lets the engine skip almost every file that does not hold the key.
The trade-off has a name: amplification
Engineers measure this trade-off with two ratios. Write amplification is bytes physically written per byte the application wrote. Read amplification is how many places must be checked for one lookup. A B-Tree rewrites a whole page (4 to 16 KB) to change a few bytes, plus the WAL entry, so it has write amplification too. An LSM-Tree rewrites each piece of data again every time compaction merges it into a bigger level, and the number depends heavily on the compaction strategy and the size ratio between levels. On the read side it is the other way round: the LSM checks several files, the B-Tree checks one path. I will not quote a single number here, because the honest answer is "it depends on your configuration and your data". DDIA says as much: LSM-Trees often sustain higher write throughput, and compaction can steal bandwidth and cause latency spikes at the tail (why those spikes hurt so much is the subject of the tail latency post).
Question two: how do we search?
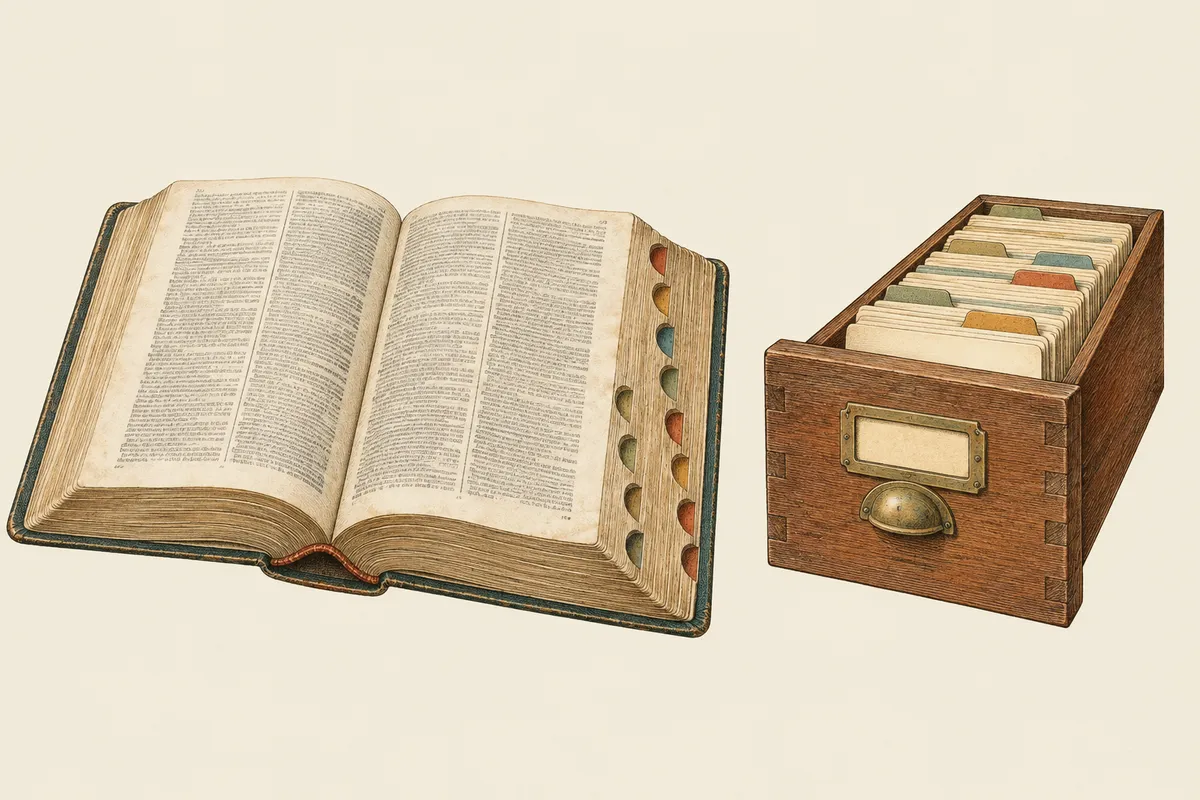
Writing is only half the story: bytes that land on disk are useless if you cannot find them again. Take a thick dictionary. You do not read it from page one. You see the thumb-index tabs along the edge, jump to the letter P, scan the top corners to find pe-, then pen, then the word. Three or four narrowing steps and you are there. A B-Tree is that: a tree of fixed-size, sorted pages, where each page holds many keys and the pointers between them, so one page narrows the search by a factor of hundreds.
The arithmetic is worth doing once. Say a page holds around 500 child pointers (the figure DDIA uses; with short keys it is plausible even for a 4 KB page). The root points to 500 children, two levels reach 250,000 pages, three levels 125 million, four levels 62.5 billion. DDIA works the same example with 4 KB pages: 62.5 billion pages times 4 KB is 256 TB, and that is the most a four-level tree can hold. So a table of a hundred million rows is 3 to 4 page reads away from any row, and the top one or two levels are almost always cached in memory, so in practice a lookup often costs one or two real disk reads. That is the "O(log n)" you keep hearing, with a base so large it feels constant.
Two honest footnotes. First, "every index in Postgres and MySQL is a B-Tree" is a good default, not a law: Postgres also offers hash, GIN, GiST and BRIN indexes for special shapes of data, though CREATE INDEX gives you a B-Tree unless you say otherwise. Second, B-Trees keep their keys sorted, and that is why they answer range queries (BETWEEN, ORDER BY) as easily as equality: find the start, then walk the leaves.
Notice that this question is independent from question one. An LSM-Tree answers it differently (a lookup consults the memtable and the SSTables through their sorted files and Bloom filters), but it still needs some way to search. That is exactly why "LSM vs B-Tree" is a slightly unfair framing: they differ most in the write column, and only indirectly in the search column.
Question three: where does the row live?
Back to the dictionary. When you reach the word apple, the definition is right there on the same line. You never flip anywhere else. The dictionary is the data itself, sorted by one rule, and because it is physically sorted by that one rule, there can be only one such arrangement. That is a clustered structure.
Now take an ordinary textbook with an index at the back: "replication, 151, 153, 160". Finding the entry is fast (the index is alphabetical, a small B-Tree of its own), but it only hands you a page number. You then flip to page 151. That is a non-clustered (secondary) index: the leaf holds a pointer, and one more hop fetches the real thing. A book can have several back-of-book indexes (names, topics, places); it cannot be physically printed in several orders.
What InnoDB and Postgres actually do
This is where textbooks (and my own first notes) get sloppy, so here it is precisely.
- MySQL InnoDB: every table is a B-Tree keyed by the primary key, and the leaves contain the full rows. The table is clustered on the primary key, always (with no declared PK, InnoDB falls back to the first unique NOT NULL index, or a hidden row id). Every secondary index stores, in its leaf, the indexed column plus the primary key value of the row (not a physical address). A lookup through a secondary index is therefore two B-Tree descents: one in the secondary index to get the PK, one in the clustered tree to get the row.
- PostgreSQL: a table is a heap, an unordered pile of pages where rows land wherever there is room. Every index is secondary, the primary key index included. Its leaf entries point to a physical location, the tuple id (page number plus slot). One descent, then one heap fetch. The command
CLUSTERdoes exist, but it is a one-off physical reorder of the heap by an index: new rows are not kept in that order afterwards, and it takes a heavy lock while it runs. So "Postgres is clustered" is wrong; "Postgres can be reordered once" is right. - SQL Server, Oracle: SQL Server lets you choose one clustered index per table or leave it a heap; Oracle's heap tables are the default and index-organized tables are the clustered variant. Same idea, different defaults.
-- MySQL / InnoDB: the PK index IS the table
CREATE TABLE users (
  id    BIGINT PRIMARY KEY,         -- clustered: leaves hold the full row
  email VARCHAR(255) NOT NULL,
  name  VARCHAR(100),
  KEY idx_email (email)             -- secondary: leaf = (email, id)
) ENGINE = InnoDB;

SELECT * FROM users WHERE id = 42;                -- one descent
SELECT * FROM users WHERE email = 'a@example.com'; -- two descents (email -> id -> row)
SELECT id FROM users WHERE email = 'a@example.com'; -- one: the PK is already in the leaf

-- PostgreSQL: the heap is not ordered by anything
CREATE INDEX users_email_idx ON users (email);
CLUSTER users USING users_email_idx;  -- reorders the heap ONCE, takes ACCESS EXCLUSIVE lock
Why this changes how you design
- Keep the InnoDB primary key short. It is copied into the leaf of every secondary index, so a 36-character UUID string as PK makes every secondary index fatter than an 8-byte integer would.
- Random primary keys scatter inserts. A clustered table keeps rows in key order, so a random UUID drops each new row into a random leaf, splitting pages all over the tree, while an auto-increment id always appends at the right edge. This is why time-ordered ids (UUIDv7, snowflake-style) are popular.
- A covering index skips the hop. If the secondary index already contains every column the query needs, the engine never visits the row: InnoDB's "Using index", Postgres's "Index Only Scan" (which also depends on the visibility map being up to date).
Where I got it wrong
Now I can admit where all this fell apart for me, and it is the embarrassing part. When I first explained these to myself, I said: "clustered means the writes are sequential." It sounds plausible, because "cluster" feels like "group" and sequential writes were the thing I had just read about in the LSM section. But I had taken the write property of the LSM-Tree and pinned it on a concept that is about placement. Clustering says nothing about how bytes get to the disk; it says where the row sits relative to the index.
The second slip was subtler. Asked which engine to pick for a service logging 50,000 events per second, I answered "LSM", correctly, and then justified it with "because reads will be fast". Wrong reason. The burden of that workload is the write rate, and the thing LSM buys you is cheap sequential writes. Reads are the part you pay extra for. Right answer, wrong question, which is a dangerous combination, because the next workload will not be so forgiving.
| Workload | Lean towards | Because |
|---|---|---|
| Writes like rain: logs, metrics, IoT, event streams | LSM-Tree (RocksDB, Cassandra) | Sequential writes; compaction pays the bill later |
| Steady reads, transactions, point and range lookups | B-Tree (Postgres, MySQL) | One predictable path per read, mature locking and MVCC |
Who picks the route: the optimizer and its statistics
A few weeks later the same DBA showed me a slow query and said only: "Before you touch the SQL, update the statistics." His note on the subject, which I have kept, is short: the optimizer chooses a plan by estimating costs, and the estimates come from statistics. Garbage in, garbage out.
The picture that made it stick for me is Google Maps. The optimizer is the app; the statistics are the live traffic data. If the traffic feed froze at 3 a.m., the app would cheerfully route you down a motorway that is now a car park. The app is not stupid; its data is stale. A database planner has the same weakness: it does not look at the table, it looks at a small summary of the table (row counts, distinct values, histograms, the most common values), and chooses between a full scan, an index scan or a bitmap scan based on that summary.
Reading a wrong plan
In Postgres, the tell is in EXPLAIN ANALYZE: compare the estimated rows with the actual rows. The output below is illustrative (the format is real, the numbers are made up to show the pattern). Picture an orders table of about 2.9 million rows that was last analyzed when almost every order was still 'new'. Since then a batch job has marked half of them 'shipped', and nobody re-ran ANALYZE:
EXPLAIN (ANALYZE)
SELECT * FROM orders WHERE status = 'shipped';

 Index Scan using orders_status_idx on orders
     (cost=0.43..5871.20 rows=1450 width=48)
     (actual time=0.031..1840.602 rows=1450000 loops=1)
   Index Cond: (status = 'shipped'::text)
 Planning Time: 0.210 ms
 Execution Time: 1862.412 ms
-- estimated rows=1450, actual rows=1450000: the planner thinks 'shipped' is 1000x rarer than it is

ANALYZE orders;   -- MySQL: ANALYZE TABLE orders;

EXPLAIN (ANALYZE)
SELECT * FROM orders WHERE status = 'shipped';

 Seq Scan on orders
     (cost=0.00..61236.00 rows=1447200 width=48)
     (actual time=0.020..310.204 rows=1450000 loops=1)
   Filter: (status = 'shipped'::text)
   Rows Removed by Filter: 1450000
 Planning Time: 0.140 ms
 Execution Time: 331.812 ms
-- the estimate now matches reality, and the plan changed on its own
My colleague's own story ran the other way: someone deleted about 90% of a big table, but the statistics still described three million rows, so the plans were tuned for a table ten times bigger than the one that existed. How a given engine reacts to a mass delete differs (Postgres, for one, rescales its row estimate using the table's current size, so the gap shows up differently), but the lesson is the same. Postgres normally refreshes statistics on its own through autovacuum, which re-analyzes a table once roughly 10% of its rows have changed by default (autovacuum_analyze_scale_factor = 0.1), and only on its next pass. After a big load, a big purge or a schema change, do not wait for that; run ANALYZE yourself. Rule of thumb: when the plan is wrong, fix the input (statistics) before you fix the output (the SQL, or a forced hint).
When the full scan is the right answer
Here is the question that bothered me most: "I updated the statistics, and it still does a full scan. Do I just put up with it?" It felt like admitting defeat. It is not. Sometimes the optimizer, now armed with correct numbers, is right and your instinct is wrong.
Do the arithmetic once. A table of 1,000,000 rows at about 100 rows per 8 KB page is 10,000 pages, roughly 80 MB. A full scan reads each page once, in order, which disks and read-ahead love. Now suppose the query wants 10% of the rows: 100,000 rows. Through a secondary index, those rows are scattered across the heap, so in the worst case that is up to 100,000 page fetches, ten times more than the whole table has, many of them random and some of them the same page read again. Even if the whole table sat in cache, 100,000 random picks among 10,000 pages touch nearly every page anyway. The index did not save work; it multiplied it.
| Factor | Pushes towards a full scan | Pushes towards the index |
|---|---|---|
| Fraction of rows returned | Large (tens of percent) | Tiny (a fraction of a percent) |
| Rows per page | Many small rows: the scan covers lots per page | Few wide rows |
| Correlation of the index with physical order | Low: matches scattered everywhere | High: matches sit together (as in a clustered index) |
| Storage | Spinning disk: random reads cost a lot | SSD, or data mostly in cache |
People quote "around 10% of the table" as the line where a full scan starts to win. Treat it as a rough heuristic, not a law. Here is why it moves. With Postgres's default cost settings (seq_page_cost 1, random_page_cost 4, cpu_tuple_cost 0.01, cpu_operator_cost 0.0025), a full scan of our 1,000,000-row table costs about 10,000 + 10,000 + 2,500 = 22,500 units. A plain index scan whose matches are scattered pays up to 4 units per row for the heap fetch alone, so it reaches 22,500 at roughly 5,600 rows, about 0.6% of the table. The real formula is gentler (fetches cannot exceed the number of pages, and the index has its own costs), so read this as a ballpark: for an uncorrelated plain index scan the break-even sits near 1%, far below 10%. A bitmap scan, which collects the matches and reads pages in physical order, wins the middle range; SSD-friendly settings (a lower random_page_cost) push every threshold higher. The number depends on your data, so measure it. You can ask the planner to show its second choice:
-- the planner's choice (illustrative numbers, 1M-row table, ~38% match)
EXPLAIN ANALYZE SELECT count(*), sum(total) FROM orders WHERE status = 'shipped';
 Aggregate  (cost=24400.00..24400.01 rows=1 width=40) (actual time=96.290..96.291 rows=1 loops=1)
   ->  Seq Scan on orders  (cost=0.00..22500.00 rows=380000 width=8) (actual time=0.021..71.302 rows=380000 loops=1)
         Filter: (status = 'shipped'::text)
         Rows Removed by Filter: 620000
 Execution Time: 96.412 ms

-- the road not taken, for this session only (diagnosis, never production config)
SET enable_seqscan = off;
EXPLAIN ANALYZE SELECT count(*), sum(total) FROM orders WHERE status = 'shipped';
 Aggregate  (cost=32400.00..32400.01 rows=1 width=40) (actual time=247.810..247.811 rows=1 loops=1)
   ->  Bitmap Heap Scan on orders  (cost=7500.00..30500.00 rows=380000 width=8) (actual time=41.002..231.510 rows=380000 loops=1)
         Recheck Cond: (status = 'shipped'::text)
         Heap Blocks: exact=10000
         ->  Bitmap Index Scan on orders_status_idx  (cost=0.00..7405.00 rows=380000 width=0) (actual time=39.800..39.800 rows=380000 loops=1)
               Index Cond: (status = 'shipped'::text)
 Execution Time: 247.931 ms
RESET enable_seqscan;Three mantras
After the full scan, the sticky note got short enough to say out loud. The first line is my own; the others are the habits I kept from the DBA's notes.
Writes like rain, go LSM. Steady reads and transactions, go B-Tree.
My note-to-self for question one
- Clustered is the dictionary (there is only one). Non-clustered is the index at the back of the book (you can have many). Question three, and it has nothing to do with how writes happen.
- A bad output means check the input. A wrong plan is a stale-statistics problem until proven otherwise; run ANALYZE first.
- A full scan is not a failure. When a query touches a large share of the table, the sequential read is the honest plan.
Back to my colleague's casual question. The honest answer was "yes to both, and those are different facts." In InnoDB the primary key index is a B-Tree (how we search) and clustered (where the row lives); how InnoDB gets pages to disk is a third thing again. Three questions, three answers, one drawer finally split into three. If you remember one habit from this post, make it the three-column sketch. Ask which question a word answers before you ask which one is better. Next in the series: what happens when the machine holding all this data dies, in the failover and split brain post.